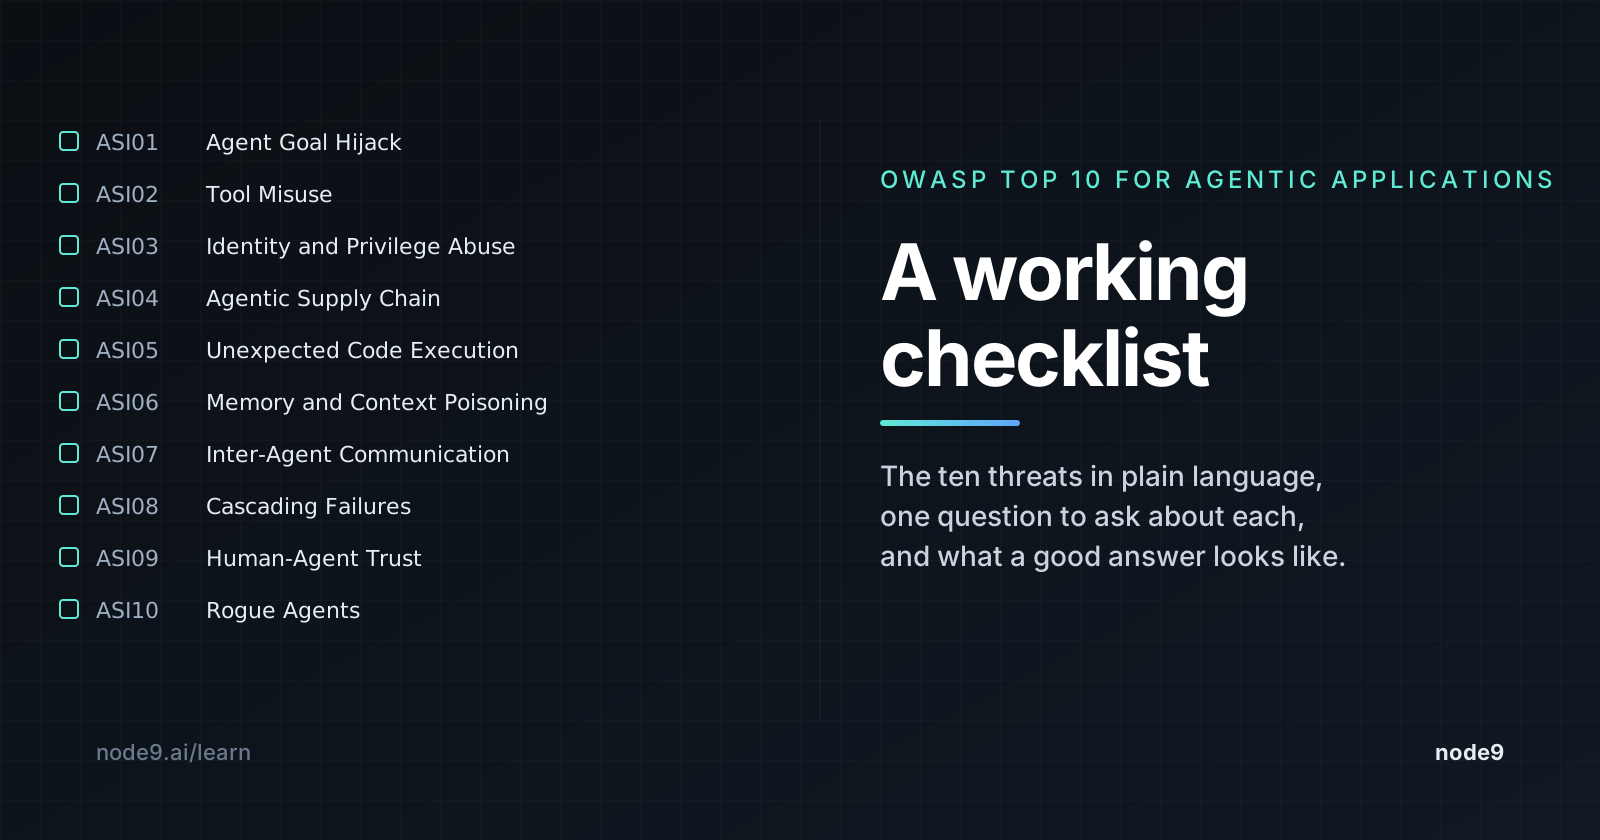
OWASP published a Top 10 for Agentic Applications because the existing lists did not fit. An agent is not a web app: it plans, it acts, it holds credentials, and it takes instructions from content it fetched. The classic categories have no row for "the input was a lie and the program believed it."
This page is the list in plain language. For each threat there is the question worth asking about your own setup, and what a good answer looks like, so you can check it today without buying anything. At the end, our own grades against the ten.
One note on reading grades, ours or anyone's. A grade describes what a control covers against known techniques. It is not a guarantee, and no tool will cover every instance of any of the ten. A vendor page that reports ten strong rows is telling you about its marketing.
The ten, and what to ask
ASI01 · Agent Goal Hijack. Content the agent fetched contains instructions, and the agent follows them. This is the root threat: a model has no reliable boundary between data it was given and instructions it was given.
Ask: is anything inspecting what comes back from a tool, or only what goes in?
Good looks like: tool output passes through a scanner before the model reads it, and an action taken right after suspicious output gets a second look.
ASI02 · Tool Misuse. The agent uses a tool it legitimately has in a way you did not intend. Not a forbidden tool. An allowed one, pointed somewhere else.
Ask: does your policy understand the structure of a call, or match its text?
Good looks like: you can write a rule that allows one form of a command and refuses another, for example git push but not git push --force, and the rule holds when the command is spelled differently.
ASI03 · Identity and Privilege Abuse. The agent acts with your identity and your credentials, and nothing downstream can tell the difference between you and it.
Ask: can you attribute any single action to an agent, a person, and a machine?
Good looks like: every line in your audit log carries all three. If it carries one, start there. And a read of a credential file is refused before it happens, however the path is spelled.
ASI04 · Agentic Supply Chain Vulnerabilities. The agent's own configuration is the supply chain: MCP servers, hooks, skills, instruction files, and the packages it installs on your behalf. All executable, few reviewed the way code is reviewed.
Ask: has anyone read your .claude/settings.json and .mcp.json as carefully as they read a dependency bump, and what checks a package before the agent installs it?
Good looks like: a diff to agent config pings a reviewer, and npm install of a package with a malicious-package advisory is refused before it runs.
ASI05 · Unexpected Code Execution. The agent runs something you did not intend, through an eval, an inline execution, or a script fetched at runtime.
Ask: does your gate read the command the agent ran, or also the contents of the script that command executes?
Good looks like: curl | sh and its PowerShell cousin iwr | iex are refused, inline python -c and node -e are reviewed, and the scripts your hooks point at are read in code review.
ASI06 · Memory and Context Poisoning. Something hostile lands in memory or in a long-lived context and influences the agent later, long after the moment it arrived.
Ask: does anything persist across sessions, and did anyone check it?
Good looks like: skill files and MCP tool lists are pinned, so a change since the pin is a finding, and instruction files are reviewed like code.
ASI07 · Insecure Inter-Agent Communication. Agents that call other agents inherit each other's trust, and the second agent has no way to know the first one was compromised.
Ask: does an instruction from another agent get the same scrutiny as one from a web page?
Good looks like: agent-to-agent traffic goes through the same gateway as tool traffic, and a response the agent did not ask for is dropped.
ASI08 · Cascading Failures. One bad decision multiplies: a loop, a fan-out, a retry storm. Sometimes the damage is money rather than data.
Ask: what stops an agent that is burning budget at 3am, and does anyone find out before the invoice?
Good looks like: a repeated identical call trips a breaker, and spend per agent is visible the same day, not at month end.
ASI09 · Human-Agent Trust Exploitation. The agent asks for approval in a way that makes yes the obvious answer, or the approval channel itself is the weak point.
Ask: does an approval prompt tell you what will actually happen, and can the agent influence what the prompt says?
Good looks like: the prompt is written by the control, not by the agent, it names the exact command and target, and a credential request always reaches a person.
ASI10 · Rogue Agents. An agent running that nobody sanctioned, or a sanctioned one that has slipped its policy.
Ask: can you list every agent running across your machines right now?
Good looks like: one command prints the agents on a machine and whether each one is governed, and a fleet view shows the same across the team.
Why a self-assessment is worth more than a vendor claim
Every tool in this space will tell you it covers the Top 10. The list is broad enough that almost anything can claim a row. The useful exercise is the opposite one: go down the ten, and for each write strong, moderate, partial, or not covered, with the evidence next to it. The rows you cannot fill are the answer.
Our own answers
We did that exercise on node9. Here is the result, with one line per row on where the coverage stops, because that line is what makes the grade worth reading.
| Threat | Grade | Where this stops |
|---|---|---|
| ASI01 Agent Goal Hijack | Partial | The injection detector ships off, and its modes are off and log. Response scanning, MCP result scanning and the review of the next action after tainted output all run; the detector itself is a setting you turn on. |
| ASI02 Tool Misuse | Strong | A command is judged by its structure before it runs. The contents of a script that command then executes are read by scan-repo in the repository, not at the gate. |
| ASI03 Identity and Privilege Abuse | Strong | Attribution covers the agents node9 is wired into. A process the agent never invoked, such as a cron job, is outside it. |
| ASI04 Agentic Supply Chain | Strong | The package check runs when the agent runs the install. An install a person types in their own terminal does not pass through node9. Skill pinning ships off. |
| ASI05 Unexpected Code Execution | Moderate | The gate reads the call the agent made. It does not read the contents of a script that call runs at run time, nor the subprocesses that script spawns. |
| ASI06 Memory and Context Poisoning | Moderate | Skill and MCP tool-list pinning detect a change since the pin. Memory and instruction files the user authored are not pinned. |
| ASI07 Insecure Inter-Agent Communication | Partial | Covered where traffic passes through a wired agent or the MCP gateway. Agent-to-agent traffic that crosses neither is not seen. |
| ASI08 Cascading Failures | Moderate | A runaway loop is blocked by default. Cost is reported per agent and per project; there is no spend ceiling or budget alert. |
| ASI09 Human-Agent Trust Exploitation | Strong | The prompt text comes from node9, not from the agent. The agent's own stated reason for wanting an action is shown, not evaluated. |
| ASI10 Rogue Agents | Strong | node9 lists and governs the agents it is wired into on each machine. An agent installed after setup is not wired until setup runs again. |
Five strong, three moderate, two partial.
Where the strong rows come from is specific rather than broad: every tool call is parsed into its structure before it runs, so policy can allow one form of a command and refuse another; credential files are refused with nothing configured, and the refusal holds when the path arrives through $HOME, a command substitution or a variable; a package with a malicious-package advisory is refused before it installs, which is what would have stopped the nx versions published in August 2025 from installing through an agent; and the cloud metadata address is refused wherever a tool declares the URL it is fetching.
The per-threat breakdown with the evidence behind each grade is at Agentic Threat Coverage.
Where to start
If you do one thing from this page, do ASI10 and ASI03 first, because they are the cheapest and they tell you the most:
npx node9-ai posture     # this machine's scorecard: secrets, egress, gate, about 60 seconds
npx node9-ai scan        # read the agents' own history and show what node9 would have caught
You cannot threat-model agents you cannot list. Start with the list.